AI mental health support assistant ad monetization is the practice of embedding contextual, brand-safe ad units inside a wellness chatbot's conversation flow with the aim of turning free-tier usage into revenue without touching a user mid-crisis. This segment doesn't behave like a customer-support bot or a shopping assistant: sessions run longer, topics swing emotional, and a meaningful share of traffic touches subjects — self-harm, disordered eating, substance use — that no advertiser wants next to their brand and no user should see monetized.
- Ad monetization for AI mental health assistants works best with native in-chat cards, hard category exclusions, and a human-reviewed brand-safety filter.
- Elo's SDK lets developers exclude crisis-adjacent topics from ad triggers and monetize only non-clinical conversation turns.
- Banner and display mediation built for web wrappers break the conversational card format and ignore session context.
- Frequency caps matter more here than in a generic chatbot — long support sessions create more inventory and more risk of a bad placement.
Why ad monetization matters for AI mental health support assistants
A free-tier wellness or support chatbot burns compute on every message, including the ones from users who will never upgrade and never should be asked to pay while they're struggling. Contextual ads let the non-clinical parts of a conversation — sleep hygiene tips, journaling prompts, a meditation app mention — carry revenue without putting a paywall in front of someone who just disclosed distress.
This segment also generates more messages per session than a typical support bot, which means more raw inventory. That's the upside. The downside is the same length of session creates more surface area for a mistimed ad to land right after a disclosure, which is the fastest way to lose trust in a product built on trust. Elo's conversational ad SDK is built around that tradeoff: contextual matching that can be told, explicitly, what topics are off-limits.
Audit your conversation categories before turning anything on
Before any ad SDK, pull a sample of real transcripts and tag what's actually being discussed. Most teams underestimate how much of their traffic is non-clinical small talk versus how much touches sensitive intents.
- Sample at least a few hundred recent sessions across peak and off-peak hours
- Tag turns as commercial-safe, neutral, or sensitive
- Flag any mention of self-harm, crisis language, or medication as sensitive by default
- Note session length and time-of-day patterns — late-night sessions skew more sensitive
- Share the tagged sample with whoever owns ad policy, not just engineering
Define hard category exclusions before matching a single ad
Exclusions come first, matching comes second. Decide what can never appear before deciding what can.
- Exclude weight-loss, dieting, and appearance-related ad categories outright
- Exclude alcohol, gambling, and dating verticals
- Exclude any advertiser category flagged as high-risk by your own policy review
- Build a keyword and intent list that suppresses ad calls entirely on crisis-adjacent turns
- Document exclusions in writing so a new hire can't silently loosen them later
Choose native ad placement over interruption formats
A banner or interstitial breaks a conversational interface in a way a native card doesn't. In a mental health context, an interruption format reads as tone-deaf even when the content itself is fine.
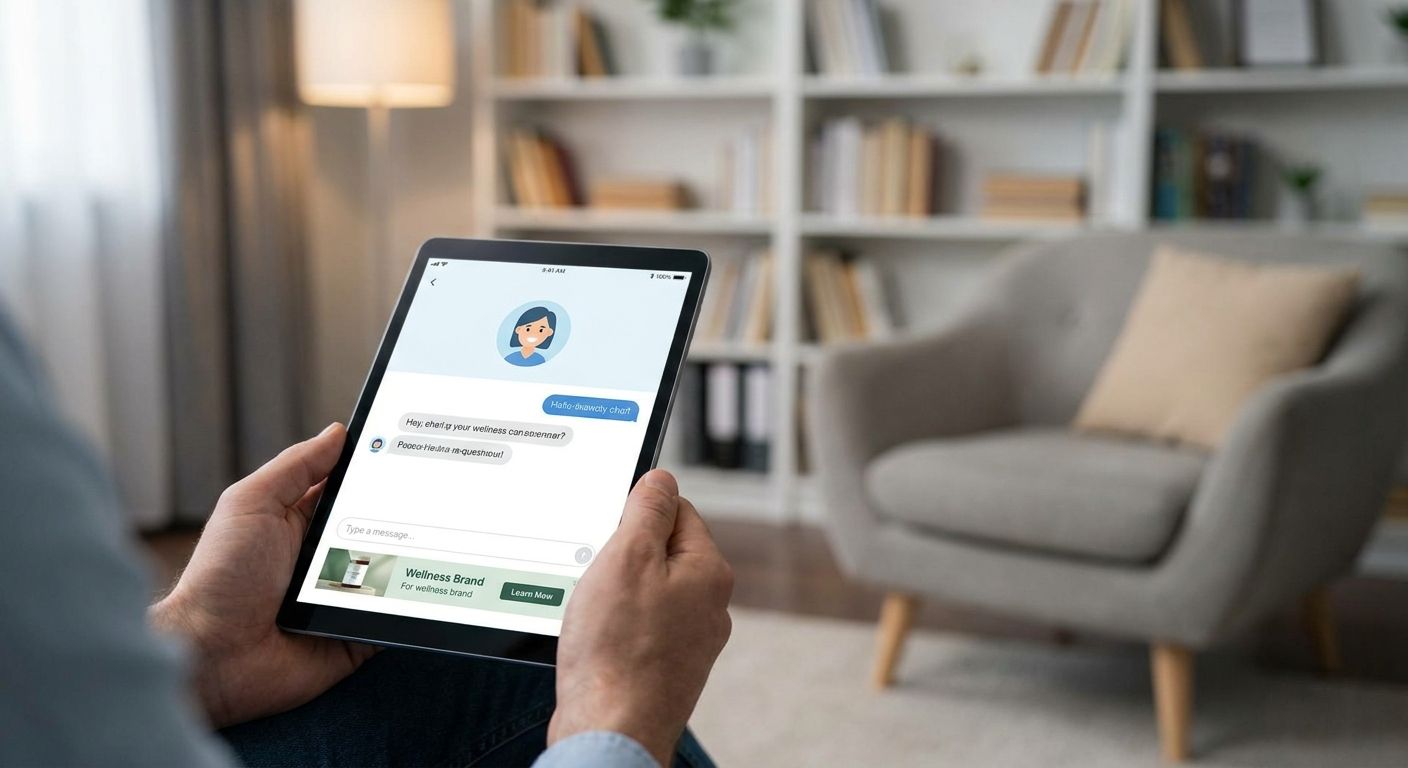
- Render ads as inline cards styled to match the chat, not overlays or pop-ups
- Cap ad units to one per response, never stacked
- Never trigger an ad on the same turn as a crisis-flagged message
- Give the user a visible way to dismiss or skip the card
- Match ad copy tone to the conversation's tone — calm, not promotional
This is where a purpose-built SDK earns its place over a generic mediation stack. Elo's ad SDK renders native cards rather than banners, and matching runs per-turn so a single flagged message doesn't get an ad slapped underneath it.
Set frequency caps and cooldowns for sensitive sessions
Long sessions mean more ad opportunities, but more isn't better here. A user in a 40-message support session doesn't want six ad cards along the way.
- Cap ad frequency per session, not just per day
- Add a cooldown window after any sensitive-flagged turn before an ad can show again
- Lower cap thresholds for sessions that opened with crisis language, even if it later normalizes
- Track skip and dismiss rates as a leading indicator of fatigue, not just click-through
- Review caps quarterly against session-length data, not once at launch
Route every match through a brand-safety filter
Contextual matching without a safety layer will eventually pair the wrong advertiser with the wrong turn. That's a compliance and trust problem, not just a UX one.
- Run every candidate ad through a keyword and topic exclusion filter before it serves
- Add a manual review pass for any new advertiser category before it goes live
- Log every served ad against the conversation turn that triggered it for later audit
- Give a human reviewer the ability to pull an advertiser instantly, not just at renewal
- Re-check exclusion lists whenever you add a new LLM prompt or feature
Elo's brand safety filtering sits at this layer — exclusions and category blocks apply before a match is ever rendered, not as a post-hoc cleanup.
Instrument revenue reporting by session type
Treating all sessions as one bucket hides where the money and the risk actually live. Split reporting by session type from day one.
- Report revenue per session type: onboarding, ongoing support, crisis-flagged
- Track fill rate and RPM separately for non-clinical versus neutral sessions
- Exclude crisis-flagged sessions from revenue targets entirely — they should show zero ad revenue by design
- Watch for drift where a growing share of "safe" sessions starts touching sensitive topics
- Review the split monthly, not quarterly — this segment's traffic mix shifts fast
Test the rollout with a limited cohort first
Don't flip ads on for 100% of users on day one. A staged rollout catches placement and exclusion problems while the blast radius is small.
- Start with a 5-10% cohort of non-clinical, low-risk sessions
- Watch skip rate, session length change, and any support tickets mentioning ads
- Expand only after a full week of clean logs with zero exclusion misses
- Keep a kill switch that disables ads instantly if a bad match slips through
- Re-run the audit from step one after any major prompt or model change
The University of your own transcript audit is more reliable than any vendor's default category list — most default lists aren't built for a wellness-specific traffic mix.
Comparing your monetization options
| Option | Best for | Key limitation |
|---|---|---|
| Native in-chat contextual ads (Elo) | Wellness and support chatbots that want revenue without breaking the conversational card feel | Needs category exclusion setup done properly before launch |
| Generic display/mediation networks | Web wrappers with visible ad space outside the chat window | Banner formats interrupt conversational UX and ignore turn-level context |
| Direct advertiser deals | Niche wellness apps with an in-house sales team and a defined audience | Manual sales cycle, low fill rate at scale |
| Ads-off, subscription-only | Clinical or crisis-focused tools where any ad exposure is a liability | Zero revenue from free-tier or non-paying users |
Native in-chat ads with hard category exclusions win for most wellness and support chatbots in 2026 — they're the only option in this table that monetizes free-tier traffic without introducing an interruption format or a manual sales bottleneck.
Set up exclusions before you launch ads
See how Elo's SDK handles category blocks and native card rendering.
Common mistakes mental health assistants make with ads
- Running direct-response ads next to a disclosure of distress. A weight-loss or dating ad served right after a user mentions feeling hopeless is the single fastest way to generate a complaint or a press screenshot.
- Treating every session as equally monetizable. A session that opens with crisis language shouldn't carry ad revenue targets at all — build that into reporting, not just policy.
- Skipping the manual review pass on new advertiser categories. Automated keyword filters miss context; a human glance before launch catches what the filter doesn't.
- No cooldown after a flagged turn. A session can normalize after a rough opening message, but the ad engine shouldn't assume that recovery happened in real time.
- Launching to 100% of traffic on day one. A staged rollout with a kill switch costs a week; a bad placement that goes viral costs a lot more than a week of lost revenue.
FAQ
What's the best way to monetize an AI mental health chatbot?
Native in-chat contextual ad cards with hard category exclusions built in before launch are the safest and best-performing format for this segment in 2026. Banner or interstitial formats break the conversational UX and read as tone-deaf in a support context.
Is native in-chat advertising safer than banner ads for mental health assistants?
Yes — native cards render inline with the conversation and can be suppressed on a per-turn basis, while banners sit outside the chat and ignore what the user just said. A banner network has no concept of a crisis-flagged turn; a contextual matcher does.
How much revenue can a wellness chatbot earn from ads?
Revenue depends on session volume, message length, and advertiser demand for the categories you allow, so there's no single figure that applies across apps. Splitting reporting by session type (onboarding, ongoing, crisis-flagged) gives a clearer read than a blended average.
Are conversational ads GDPR compliant for AI mental health apps?
Compliance depends on how consent, data handling, and ad targeting are configured in the SDK you choose, not on the ad format itself. Review the specifics of consent flows and targeting scope before launch rather than assuming any vendor is compliant by default.
How do you stop ad exclusions from missing crisis conversations?
Combine a keyword/intent exclusion list with a cooldown window after any flagged turn, and review the list monthly against real transcripts. A static list built once at launch drifts out of date as user language and prompts change.
Can a mental health chatbot run ads without hurting user trust?
Yes, if placement is native, frequency is capped, and sensitive turns are excluded from matching entirely. Trust erodes when ads feel commercial or mistimed, not when ads exist at all.
Does Elo's SDK support brand-safety filtering for sensitive topics?
Elo's conversational ad SDK filters candidate ads against exclusion rules before a match renders, and supports manual review of new advertiser categories before they go live. That filtering layer sits ahead of the matcher, not after.
One last thing
The highest-leverage move for this segment isn't the ad network you pick — it's the exclusion list you write before you pick one. Most teams spend weeks comparing SDKs and an afternoon on category exclusions; flip that ratio. A wellness chatbot that gets the exclusion list right can run native ads on the majority of non-clinical sessions in 2026 without a single bad placement reaching a distressed user, and that record is what actually protects the ad revenue line long-term, not the vendor logo.