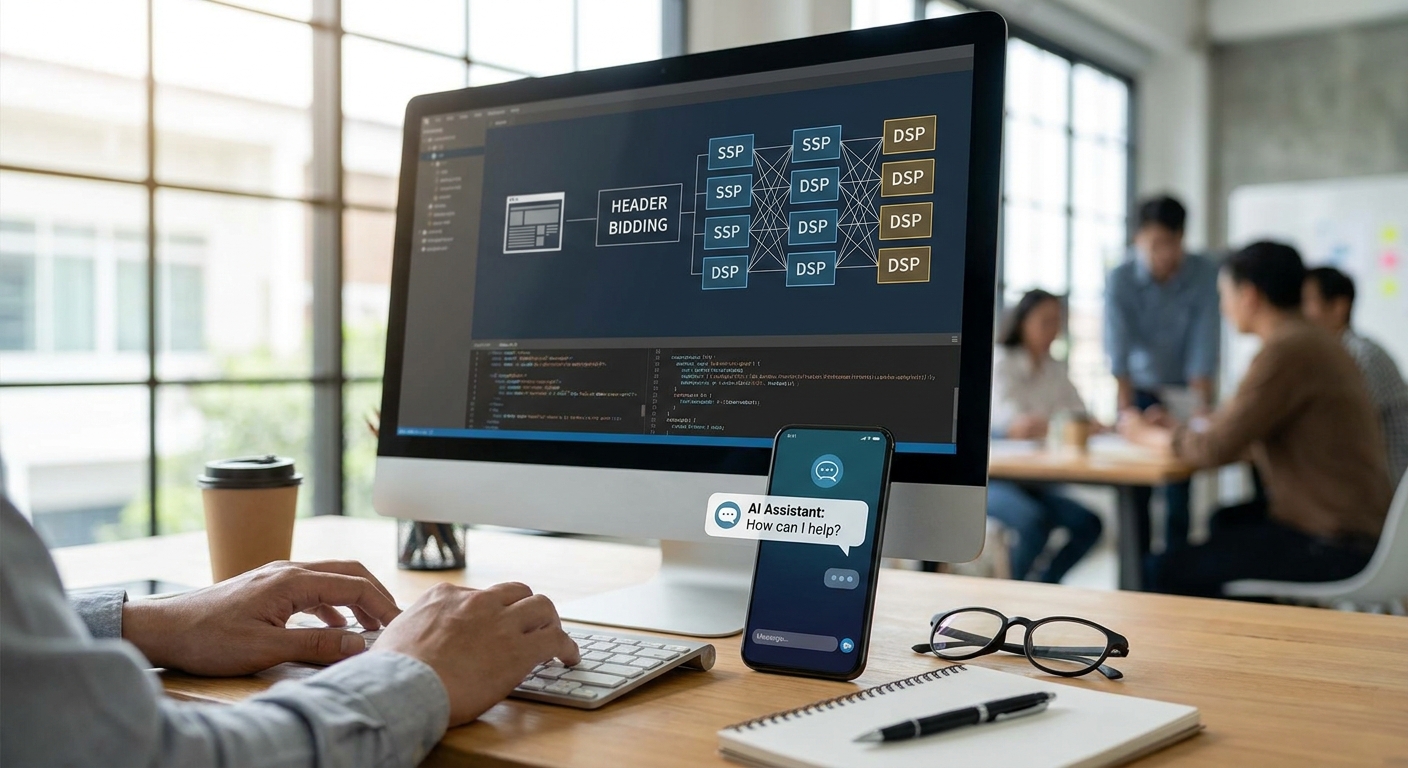
Header bidding for an AI chat app means letting multiple ad networks compete for the same conversational ad slot in real time, instead of routing every impression through a single waterfall. This guide walks through the setup end to end: auditing your current stack, wiring parallel bid requests into a chat turn, setting contextual floors, and catching the mistakes that stall a launch in 2026.
- Header bidding for an AI chat app replaces single-network waterfalls with real-time bidding across networks per chat turn.
- A mediation SDK like Elo runs parallel bid requests instead of sequential fallback calls — cuts latency and lifts RPM.
- Bid floors should key off conversation context, not a flat session-level CPM.
- Test the auction in staging first — mismatched floors are the top cause of under-fill after launch.
- Verdict: build on a mediation SDK, not a hand-rolled waterfall — Buy this approach for any chat app shipping ads in 2026.
Why this matters
A waterfall calls one ad network, waits for a response, and only moves to the next network if that call times out or returns no fill. Every extra hop adds latency inside a live chat turn, and the network with the biggest advertiser demand doesn't always sit first in line. Header bidding fixes that by sending the ad request to every eligible network at once and awarding the slot to the highest bid, which is why display and mobile publishers moved off waterfalls years ago.
AI chat apps have the same problem, plus a wrinkle: the "ad slot" isn't a static banner position, it's a moment inside a conversation. That means the auction has to run fast enough not to stall the model's response, and the winning creative has to match what the user just asked about. Ad mediation platforms built for conversational apps handle both constraints — the auction logic and the context match — in one layer instead of stitching several SDKs together.
Getting this wrong costs revenue twice: once from under-fill when the top network doesn't answer in time, and again from leaving money on the table when a lower-CPM network wins a slot a higher bidder would have taken.
What you'll need
- An existing ad-enabled chat app (OpenAI, Anthropic, or a custom LLM stack) with at least one ad network already integrated
- A mediation SDK that supports concurrent bid requests, not sequential fallback
- Contracts or self-serve access with two or more demand sources
- A staging environment that mirrors production traffic patterns
- Logging on every bid request and response — timestamp, network, bid price, win/loss
- 2026 revenue targets or a current RPM baseline to measure lift against
The steps
1. Audit your current ad inventory and agreements
List every ad slot your chat app currently serves — end-of-turn cards, inline suggestions, sponsored recommendations — and which network fills each one today. Pull your last 30 days of fill rate and eCPM per network. Most single-network setups show fill rates under 60% during peak hours because one demand source can't cover every query category. Skipping this step means you're guessing at which slots actually need competition.
2. Pick a mediation layer that supports concurrent bidding
Swap the waterfall for a layer that sends parallel bid requests and holds a short auction window, typically under 200ms, before rendering the winning ad. Setting up ad mediation across multiple ad networks is the point where most teams either build custom auction logic or adopt an SDK — building it yourself means owning bid timeout handling, currency normalization, and win-notification logic on your own.
3. Define ad slots per conversation turn, not per session
A chat session might run 20 turns; only a handful are natural ad moments. Tag each eligible turn type (product question, comparison request, booking intent) as its own slot so the auction can price them separately. Treating the whole session as one slot flattens pricing and undersells your highest-intent turns.
4. Set contextual bid floors
A flat $2 CPM floor across every turn ignores the fact that a shopping-intent turn is worth more to an advertiser than a general knowledge question. Set floors by context category and revisit them monthly. Common mistake: copying a mobile app's banner floor onto a chat slot — chat inventory converts differently and often clears at a different price point than banner CPMs.
5. Wire up parallel bid requests
Each eligible network gets the request at the same time, with a shared timeout. The auction closes on either the timeout or when all networks respond, whichever comes first. Log every response even when it loses — you'll need that data in step 8.
6. Test the auction end to end in staging
Run synthetic conversations through every slot type and confirm the auction picks the highest bid, not just the fastest responder. Testing ad SDK integration before launch catches timeout misconfigurations and duplicate-impression bugs before they hit production traffic.
7. Launch with full bid logging
Ship to a small percentage of traffic first — 10% is a reasonable start for 2026 launches — and watch bid response times, win rates by network, and any latency added to the chat's overall response time. Common mistake: launching to 100% of traffic on day one and discovering a network's SDK adds 400ms of latency after the fact.
8. Monitor RPM by network and adjust floors weekly
Once live, pull RPM broken out by network and by conversation context weekly for the first month. Networks that consistently win at floor price are underpriced; raise the floor. Networks that never win are either misconfigured or genuinely uncompetitive for your inventory — pause and re-evaluate.
See how Elo runs the auction
One SDK handles mediation, context matching, and bid logging.
Troubleshooting
- Auction adds noticeable latency to chat responses — shorten the bid timeout window; a 200ms cap keeps the auction invisible inside normal model response time.
- One network wins nearly every slot — check whether its bid is genuinely highest or whether other networks are timing out before they can respond.
- Fill rate drops after adding a new network — verify the new network's floor isn't set above what it can actually clear; an unreachable floor produces no-bids, not higher prices.
- Bid discrepancy between reported and actual revenue — this usually traces back to currency mismatches or a network reporting gross instead of net CPM; reconcile against your own impression logs, not the network's dashboard alone.
- Duplicate impressions logged for one turn — check for a race condition where a late bid response renders after the auction already closed and picked a winner.
- Consent or region rules block certain networks from bidding — confirm your mediation layer passes consent signals with every bid request, not just at session start.
Tools and resources
- A mediation SDK that handles concurrent requests, timeout logic, and win notification in one integration
- Bid-level logging (timestamp, network, price, context tag) exported somewhere queryable
- A staging environment with synthetic traffic across every conversation-intent category
- Context-tagging logic so bid requests carry the conversation category, not just a generic ad-slot ID
- A weekly RPM-by-network report — the single most useful artifact for tuning floors
What to do next
Once the auction is live and floors are tuned, the next question is whether revenue per user is actually moving in the direction you expected. Pull RPM by network for two weeks before making a second round of floor changes — one week of data is usually noise, not signal.
FAQ
What is header bidding for an AI chat app?
Header bidding for an AI chat app is running a real-time auction across multiple ad networks for the same conversational ad slot, instead of calling networks one at a time in a waterfall. The highest bid wins the slot inside the chat turn.
Is header bidding better than a waterfall for chat apps?
Yes for most chat apps with two or more demand sources, because parallel bidding lets the highest-paying network win every slot instead of whichever network happens to sit first in a fixed sequence. The tradeoff is added integration complexity to manage concurrent requests and timeouts.
How much latency does header bidding add to a chat response?
A well-configured auction adds under 200 milliseconds if the bid timeout is set correctly, which is usually not noticeable inside normal LLM response times. Poorly configured timeouts, often left at default values from mobile SDKs, can add 400 milliseconds or more.
Do I need multiple ad networks to use header bidding?
Yes, header bidding only makes sense with at least two competing demand sources; with one network there's nothing to auction against. Most teams start with two networks and add a third once fill rate and RPM data justify it.
How do I set bid floors for conversational ad slots?
Set floors by conversation context category rather than a flat session-wide price, since shopping-intent turns typically clear at different prices than general knowledge turns. Revisit floors monthly using RPM-by-network data from the prior weeks.
Can header bidding work with a custom LLM chatbot?
Yes, header bidding is agnostic to the underlying model — it operates at the ad-slot and bid-request layer, not the model layer. A custom LLM app needs the same mediation SDK integration as an OpenAI or Anthropic-based app.
What causes low fill rate after setting up header bidding?
Low fill rate after switching to header bidding usually means a bid floor is set above what networks can actually clear, or a bid timeout is too short for slower networks to respond. Checking no-bid logs by network isolates which one.
How often should I review header bidding performance?
Review RPM by network and by conversation context weekly for the first month after launch, then move to a monthly cadence once floors stabilize. Weekly reviews in the early period catch misconfigured floors before they cost meaningful revenue.
One last thing
Most teams tune floors once at launch and never touch them again — the actual gains in 2026 come from the weekly adjustment cycle in step 8, not the initial auction setup. A network that wins every slot at floor price for two weeks straight is underpriced, and that gap compounds every day it goes unfixed.